
SnowPro Advanced: Administrator Questions and Answers
C. reating a stream on a standard table requires the CREATE STREAM privilege on the target schema and SELECT on the source table. The role also needs USAGE on the parent database and schema to access objects in that location.
An Administrator loads data into a staging table each day. After it is loaded, users from several different departments transform the data and load it into different production tables.
How should the staging table be created and used to MINIMIZE storage costs and MAXIMIZE performance?
Options:
Create it as an external table, which will not incur Time Travel costs.
Create it as a transient table with a retention time of 0 days.
Create it as a temporary table with a retention time of 0 days.
Create it as a permanent table with a retention time of 0 days.
Answer:
BExplanation:
Snowflake transient tables are designed for intermediate or reproducible data that must persist beyond an individual session but does not require the complete recovery protections of permanent tables.
In this scenario, multiple departments access the same staging dataset through separate user sessions. A transient table provides persistent, shared access while avoiding the additional storage overhead associated with Fail-safe.
Configuring DATA_RETENTION_TIME_IN_DAYS to zero eliminates the normal Time Travel retention period, minimizing historical storage consumption.
An appropriate implementation is:
CREATE TRANSIENT TABLE STAGING_DATA
(
RECORD_ID NUMBER,
SOURCE_VALUE VARCHAR
)
DATA_RETENTION_TIME_IN_DAYS = 0;
Option A is unsuitable because external tables reference files in external storage and may introduce additional query overhead during repeated transformations.
Option C is incorrect because temporary tables are session-scoped and are not suitable for shared departmental processing across independent sessions.
Option D retains the seven-day Fail-safe protection associated with permanent tables, even when Time Travel retention is configured as zero.
Option B therefore provides the most appropriate balance of shared accessibility and reduced storage charges.
Technical qualification: Transient tables use native Snowflake storage, but they are not inherently faster than equivalent permanent tables. Their principal advantage here is lower recovery-related storage overhead. The staging dataset must be reproducible because it cannot be recovered after its applicable retention period expires.
Official Snowflake references: Working with Temporary and Transient Tables; Understanding Storage Costs.
An Administrator has been asked to support the company’s application team, which needs to build a loyalty program for its customers. The customer table contains Personally Identifiable Information (PII), and the application team has the DEVELOPER role.
C. REATE TABLE customer_data (
customer_first_name string,
customer_last_name string,
customer_address string,
customer_email string,
... some other columns,
);
The application team needs access to the customer data, but the email field must be obfuscated. How can the Administrator safeguard the sensitive information while retaining the data’s usability?
Options:
Create a view on the customer_data table to eliminate the email column by omitting it from the SELECT clause. Grant the role DEVELOPER access to the view.
Create a separate table for all the non-PII columns and grant the role DEVELOPER access to the new table.
Use the CURRENT_ROLE and CURRENT_USER context functions to integrate with a secure view and filter the sensitive data.
Use the CURRENT_ROLE context function to integrate with a masking policy on the fields that contain sensitive data.
Answer:
DExplanation:
Snowflake Dynamic Data Masking provides a suitable mechanism for controlling the visibility of personally identifiable information without creating duplicate datasets or removing columns from application queries.
Option D is correct because a masking policy can evaluate the querying role through the CURRENT_ROLE context function and return either the original column value or an obfuscated representation.
For example, an administrator can create a policy that reveals customer email addresses only to an authorized role:
CREATE MASKING POLICY email_mask AS
(val STRING) RETURNS STRING - >
CASE
WHEN CURRENT_ROLE() = 'PII_ADMIN' THEN val
ELSE '********'
END;
The policy can then be attached to the customer_email column. Developers retain access to the required table structure while receiving masked email values.
Option A completely removes the email column from the exposed view rather than preserving the field with obfuscated content.
Option B introduces redundant storage and additional data-maintenance requirements.
Option C could support specialized security-view logic, but it does not directly express the required column-level masking mechanism.
Snowflake evaluates masking policies at query runtime, allowing centralized policy management without physically modifying stored data. Administrators should also consider IS_ROLE_IN_SESSION when role hierarchy or secondary-role behavior must influence masking decisions.
Official Snowflake references: Understanding Dynamic Data Masking; CREATE MASKING POLICY; Advanced Column-level Security Topics.
Which roles may be used to create network policies in Snowflake accounts?
Choose three
Options:
SYSADMIN
SECURITYADMIN
ACCOUNTADMIN
ORGADMIN
Any role with the global permission of CREATE NETWORK POLICY
Any rote that owns the database where the network policy is created
Answer:
B, C, EExplanation:
Snowflake network policies are account-level security objects that control inbound connectivity through permitted and blocked network locations.
Creating a network policy requires the account-level CREATE NETWORK POLICY privilege. Snowflake assigns this privilege to SECURITYADMIN and higher roles by default.
Therefore, SECURITYADMIN can create network policies through its predefined security-administration capabilities. ACCOUNTADMIN can also create them because its role hierarchy includes the necessary administrative privileges.
Additionally, Snowflake permits authorized administrators to delegate the global CREATE NETWORK POLICY privilege to custom roles. Such a custom role can create network policies without requiring the complete privileges associated with SECURITYADMIN or ACCOUNTADMIN.
An example is:
GRANT CREATE NETWORK POLICY
ON ACCOUNT
TO ROLE NETWORK_SECURITY_ADMIN;
Option A is incorrect because SYSADMIN does not possess this privilege by default. Option D is incorrect because ORGADMIN focuses on organization-level administration rather than automatically inheriting account-level network-policy privileges.
Option F is incorrect because network policies are not database objects. Ownership of an individual database does not confer authority to create account-level network policies.
Following creation, policy assignment and modification remain subject to the appropriate access-control requirements. Administrators should delegate only those privileges necessary to support the intended security operations.
Official Snowflake references: CREATE NETWORK POLICY; Controlling Network Traffic with Network Policies; Access Control Privileges.
What requirements apply when creating a new account in a Snowflake organization?
Choose two
Options:
The account requires at least one ORGADMIN rote within one of the organization's accounts.
The account name is immutable and cannot be changed.
The account name must be specified when the account is created.
The account name must be unique among all Snowflake customers.
The account name must be unique within the organization.
Answer:
C, EExplanation:
Snowflake identifies accounts within an organization using an account name combined with an organization identifier. The CREATE ACCOUNT statement requires the account name as part of its syntax.
Option C is correct because administrators must specify an account name when creating an account.
Option E is correct because account names must be unique within their respective Snowflake organization. This restriction applies across the organization's supported cloud platforms and regions.
Option A is not an account-creation naming requirement. The original wording assumes the legacy ORGADMIN administration model, whereas Snowflake also supports GLOBALORGADMIN in a dedicated organization account.
Option B is incorrect because Snowflake allows organization administrators to rename accounts through ALTER ACCOUNT or the supported administration interface.
Option D is incorrect because account names are not required to be globally unique across unrelated Snowflake organizations. Instead, the combination of organization name and account name provides the globally distinguishable identifier.
Account renaming changes the preferred account URL, but Snowflake supports preservation of the previous URL when appropriate.
For production account provisioning, administrators should choose account names that reflect business purpose, environment, and regional requirements while complying with Snowflake's identifier restrictions.
Official Snowflake references: CREATE ACCOUNT; Account Identifiers; Renaming an Account.
Which Snowflake objects can be managed through SCIM integration?
Choose two
Options:
Stages
Users
Warehouses
Roles
Shares
Answer:
B, DExplanation:
Snowflake supports System for Cross-domain Identity Management (SCIM) 2.0 to automate provisioning and lifecycle administration of identities received from external identity providers.
Option B is correct because SCIM enables identity providers to create, update, deactivate, and manage Snowflake users.
Option D is correct because Snowflake maps SCIM groups from an identity provider to Snowflake account roles. Identity-provider group membership can therefore determine which Snowflake roles are assigned to provisioned users.
For example, an organization may configure an identity-provider group named DATA_ANALYST to map to a corresponding Snowflake role. When an employee is added to that group, the SCIM integration can synchronize the corresponding role assignment.
Option A is incorrect because stages are database objects administered through Snowflake SQL and object privileges, not SCIM provisioning.
Option C is incorrect because warehouse creation and configuration belong to Snowflake compute administration.
Option E is incorrect because shares are managed through Snowflake's Secure Data Sharing and access-control mechanisms.
Technical qualification: Snowflake SCIM provisioning requires the appropriate SCIM provisioning role to own the users and roles it manages. If ownership is transferred away from that provisioning role, identity-provider updates may fail to synchronize correctly. SCIM manages identity objects; it does not independently configure all downstream database permissions.
Official Snowflake references: Snowflake SCIM Support; SCIM Group API Reference.
Which role or roles should be used to correctly create the object needed to configure an OAuth 2.0 integration?
Options:
Any role with GRANT USAGE on SECURITY INTEGRATION
ACCOUNTADMIN and SYSADMIN
ACCOUNTADMIN and SECURITYADMIN
ACCOUNTADMIN only
Answer:
DExplanation:
Snowflake configures OAuth 2.0 authentication through a security integration created using the CREATE SECURITY INTEGRATION statement. The integration defines the relevant OAuth authentication and authorization settings, depending on whether Snowflake OAuth or External OAuth is implemented.
Creating an OAuth security integration requires the global CREATE INTEGRATION privilege on the Snowflake account.
The ACCOUNTADMIN system role possesses this privilege by default. Therefore, ACCOUNTADMIN is the appropriate selection when evaluating the standard system-role configuration without additional privilege delegation.
Option A is incorrect because USAGE on an existing security integration does not provide authority to create a new integration.
Options B and C are incorrect because neither SYSADMIN nor SECURITYADMIN is inherently required to participate in creation. These roles also do not receive the required CREATE INTEGRATION privilege merely through their default administrative responsibilities.
The following statement illustrates the intended administrative context:
USE ROLE ACCOUNTADMIN;
CREATE SECURITY INTEGRATION oauth_integration
TYPE = OAUTH
ENABLED = TRUE
OAUTH_CLIENT = CUSTOM;
```
Additional integration parameters may be required depending on the OAuth implementation.
Verification qualification: The phrase "ACCOUNTADMIN only" is technically too restrictive. Snowflake explicitly permits the CREATE INTEGRATION privilege to be granted to other roles. Thus, D is the intended answer for default system-role privileges, but not an absolute authorization rule.
Official Snowflake references: CREATE SECURITY INTEGRATION (Snowflake OAuth); CREATE SECURITY INTEGRATION (External OAuth); Configure Snowflake OAuth for Partner Applications.
An Administrator must configure a Snowflake virtual warehouse for a new use case with these details:
B. etween 50 and 100 concurrent users will run reports.
C. osts must be minimized according to the number of users active at a particular time.
The virtual warehouse must automatically suspend and resume based on user activity.
Which configuration meets these requirements?
Options:
CREATE OR REPLACE WAREHOUSE reporting_wh
WAREHOUSE_SIZE = MEDIUM
AUTO_SUSPEND = 600
AUTO_RESUME = TRUE;
CREATE OR REPLACE WAREHOUSE reporting_wh
WAREHOUSE_SIZE = XXXLARGE
MAX_CLUSTER_COUNT = 10
SCALING_POLICY = STANDARD
AUTO_SUSPEND = 600
AUTO_RESUME = FALSE;
CREATE OR REPLACE WAREHOUSE reporting_wh
WAREHOUSE_SIZE = XXXLARGE
AUTO_SUSPEND = 60
AUTO_RESUME = TRUE;
CREATE OR REPLACE WAREHOUSE reporting_wh
WAREHOUSE_SIZE = MEDIUM
MAX_CLUSTER_COUNT = 10
SCALING_POLICY = STANDARD
AUTO_SUSPEND = 600
AUTO_RESUME = TRUE;
Answer:
DExplanation:
Snowflake multi-cluster warehouses are designed to address fluctuating query concurrency by adding and removing compute clusters according to workload demand.
Option D creates a Medium-sized warehouse with a maximum of ten clusters and the STANDARD scaling policy. Because MIN_CLUSTER_COUNT is not explicitly specified, Snowflake uses its default value of one.
The resulting configuration operates in auto-scale mode, allowing Snowflake to increase the number of running clusters when concurrency rises and decrease it when demand subsides.
AUTO_SUSPEND=600 configures the warehouse to suspend after approximately ten minutes of inactivity. AUTO_RESUME=TRUE allows Snowflake to restart it automatically when eligible queries arrive.
Option A provides automatic suspension and resumption but creates only a single-cluster warehouse.
Option B configures multiple clusters but disables automatic resumption and assigns an unnecessarily large cluster size.
Option C also uses a large single-cluster configuration without horizontal concurrency scaling.
Therefore, D most closely meets the requirements.
Technical qualification: Multi-cluster warehouses require Enterprise Edition or higher. Additionally, STANDARD scaling prioritizes reducing query queues, while ECONOMY scaling more aggressively conserves credits. Therefore, D is the best available answer, but it is not necessarily the minimum-cost configuration for every workload.
Official Snowflake references: Multi-cluster Warehouses; CREATE WAREHOUSE; Warehouse Considerations.
In general, monthly database-replication billing is proportional to which variables?
Choose two
Options:
The frequency of changes to the primary database as a result of data loading or DML operations
The amount of table data in the primary database that changes as a result of data loading or DML operations
The frequency of the secondary database refreshes from the primary database
The number of times data moves across regions and/or cloud service providers between the primary and secondary database accounts
The number and size of warehouses defined in the primary account
Answer:
B, CExplanation:
Snowflake database replication incurs costs associated with transferring changed data and performing replication operations. These expenses are attributed to the target account containing the secondary database.
Option B is correct because the volume of modified table data affects the amount of information that must be synchronized. Large INSERT, UPDATE, DELETE, and data-loading operations can increase replication activity and its associated charges.
Option C is correct because the secondary database's refresh frequency influences the overall replication workload. More frequent synchronization can create additional replication processing and transfer activity.
Snowflake explicitly identifies changed data volume and refresh frequency as the principal variables influencing monthly replication charges.
Option A concerns the frequency of individual source modifications rather than the documented billing dimensions. Numerous small changes and a smaller number of large changes can produce very different replication volumes.
Option D describes aspects of cross-region data movement, which can affect transfer pricing, but it is not the general cost-driver formulation requested by the question.
Option E is incorrect because replication is performed using Snowflake-managed resources rather than the primary account's virtual warehouse configuration.
Current-version qualification: Snowflake now documents multiple replication billing modes, including Replication Classic, Optimized Refresh, and RPO Assurance. Their compute charging models differ, but replicated data volume and refresh behavior remain important cost considerations.
Official Snowflake references: Understanding Replication Cost: Estimating and Controlling Costs.
What is needed for credential-free stages to restrict data exfiltration after a storage integration and its associated stages have been created?
Options:
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION = true;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION = true;
ALTER ACCOUNT my_account SET
PREVENT_UNLOAD_TO_INLINE_URL = false;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION = false;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION = false;
ALTER ACCOUNT my_account SET
PREVENT_UNLOAD_TO_INLINE_URL = true;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION = false;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION = false;
ALTER ACCOUNT my_account SET
PREVENT_UNLOAD_TO_INLINE_URL = false;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION = true;
ALTER ACCOUNT my_account SET
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION = true;
ALTER ACCOUNT my_account SET
PREVENT_UNLOAD_TO_INLINE_URL = true;
Answer:
DExplanation:
Snowflake provides account-level security parameters that restrict how external stages are created and used, reducing opportunities for unauthorized data extraction through external cloud storage.
Option D correctly enables all three protective controls.
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION=TRUE requires newly created named external stages accessing private cloud storage to reference a storage integration rather than explicitly supplied cloud credentials.
REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION=TRUE requires loading and unloading operations involving private cloud storage to use an authorized external stage backed by a storage integration.
PREVENT_UNLOAD_TO_INLINE_URL=TRUE prevents ad hoc unloading directly to cloud storage URLs through COPY INTO statements.
Option A leaves inline URL unloading permitted, creating an unnecessary exfiltration pathway.
Option B disables both storage-integration requirements, allowing other credential-based configurations.
Option C disables all three controls and therefore provides the weakest protection.
Technical qualification: These parameters constrain specified data-loading and unloading mechanisms; they do not eliminate every possible data-exfiltration pathway. Administrators should also consider stage privileges, storage integration permissions, network controls, and restrictions on unloading to internal stages.
Official Snowflake references: Parameters: REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_CREATION; REQUIRE_STORAGE_INTEGRATION_FOR_STAGE_OPERATION; PREVENT_UNLOAD_TO_INLINE_URL.
A Snowflake organization, MYORG, contains two Snowflake accounts:
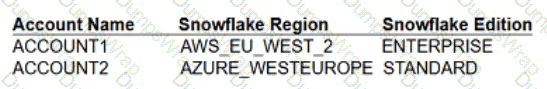
ACCOUNT1 has a database named PROD_DB and has the ORGADMIN role enabled. Management wants PROD_DB replicated to ACCOUNT2.
Options:
re any configuration steps required in ACCOUNT1 before database replication can be configured and started in ACCOUNT2?
USE ROLE ORGADMIN;
SELECT SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER(
'MYORG.ACCOUNT1',
'ENABLE_ACCOUNT_DATABASE_REPLICATION',
'TRUE'
);
SELECT SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER(
'MYORG.ACCOUNT2',
'ENABLE_ACCOUNT_DATABASE_REPLICATION',
'TRUE'
);
USE ROLE ACCOUNTADMIN;
ALTER DATABASE PROD_DB
ENABLE REPLICATION TO ACCOUNTS MYORG.ACCOUNT2;
USE ROLE ORGADMIN;
SELECT SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER(
'MYORG.ACCOUNT1',
'ENABLE_ACCOUNT_DATABASE_REPLICATION',
'TRUE'
);
USE ROLE ACCOUNTADMIN;
ALTER DATABASE PROD_DB
ENABLE REPLICATION TO ACCOUNTS MYORG.ACCOUNT2
IGNORE EDITION CHECK;
No configuration steps are necessary in ACCOUNT1. Replicating databases across accounts within the same Snowflake organization is enabled by default.
It is not possible to replicate a database from an Enterprise edition Snowflake account to a Standard edition Snowflake account.
Answer:
AExplanation:
Snowflake supports replication of databases between accounts belonging to the same organization, including accounts in different cloud providers and regions.
Option A correctly performs two prerequisites. First, an organization administrator enables replication for both the source and destination accounts by calling SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER with ENABLE_ACCOUNT_DATABASE_REPLICATION set to TRUE.
Second, an appropriately authorized account administrator enables replication on PROD_DB and explicitly identifies ACCOUNT2 as an approved destination.
Option B is incorrect because it does not enable replication for ACCOUNT2. Additionally, IGNORE EDITION CHECK is not necessary when the primary account uses Enterprise Edition and the destination uses Standard Edition.
Snowflake reserves that override for specified circumstances involving Business Critical or higher editions and lower-edition destination accounts or related compliance differences.
Option C is incorrect because the required replication features must be enabled for participating accounts.
Option D is incorrect because Snowflake supports database replication from Enterprise Edition to Standard Edition.
Current-version qualification: These commands represent the legacy database-replication workflow. Snowflake now supports replication groups and recommends group-based replication for broader business-continuity configurations. The ORGADMIN role is also being phased out in favor of GLOBALORGADMIN in a dedicated organization account.
Official Snowflake references: SYSTEM$GLOBAL_ACCOUNT_SET_PARAMETER; ALTER DATABASE; Introduction to Replication and Failover Across Multiple Accounts.
A Snowflake Administrator uses a multi-cluster virtual warehouse in the Snowflake Business-Critical edition. The minimum cluster count is set to 2, and the maximum cluster count is set to 10. This configuration performs well for the normal workload, which seldom exceeds 5 running clusters. However, once each month, several complex long-running queries increase queue time and cause the warehouse to reach its maximum of 10 clusters.
Which solutions will resolve the issues that occur once a month?
Choose two
Options:
Use a task to increase the cluster size for the time period that the more complex queries are running and another task to reduce the size of the cluster once the complex queries complete.
Have the group running the complex monthly queries use a separate appropriately-sized warehouse to support their workload.
Increase the multi-cluster maximum to 20 or more clusters.
Examine the complex queries and determine if they can be made more efficient using clustering keys or materialized views.
Increase the minimum number of clusters started in the multi-cluster configuration to 5.
Answer:
B, DExplanation:
Snowflake multi-cluster warehouses primarily address query concurrency rather than the computational demands of individual complex statements. Increasing the number of clusters allows additional queries to execute concurrently, but does not necessarily reduce the execution time of an individual query.
Option B is appropriate because a separate, correctly sized warehouse isolates the monthly analytical workload from regular reporting activity. This prevents resource-intensive queries from consuming capacity needed by everyday users. It also allows independent warehouse sizing, scheduling, and cost monitoring.
Option D addresses the underlying workload. Appropriate clustering keys can improve micro-partition pruning, while materialized views can reduce repeated scanning and aggregation. Both techniques should be evaluated against actual query profiles.
Option A introduces scheduled resizing, which could help in some circumstances but requires accurate workload scheduling and might increase compute costs unnecessarily.
Option E increases baseline capacity without resolving inefficient statements and can increase running costs.
Current-version qualification: Option C is no longer categorically invalid. Snowflake now supports more than ten clusters for eligible warehouse sizes, including up to 40 clusters for a 2X-Large warehouse. Increasing the maximum can reduce concurrency-related queueing, although it does not necessarily improve individual query execution time.
Therefore, B and D are the strongest two answers, but C is conditionally valid under current Snowflake capabilities, making the question potentially ambiguous without additional warehouse-size information.
Official Snowflake references: Multi-cluster Warehouses; Limiting Concurrently Running Queries; Working with Materialized Views.
A Snowflake Administrator needs to retain all virtual warehouse configurations for auditing and backup. A table already exists with this schema:
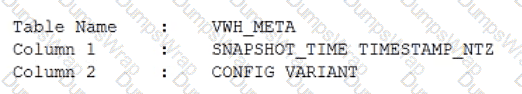
Which commands should be run to persist the warehouse data at execution time in JSON format in the VWH_META table?
Options:
1. SHOW WAREHOUSES;
2. INSERT INTO VWH_META
SELECT CURRENT_TIMESTAMP(),
FROM TABLE(RESULT_SCAN(LAST_QUERY_ID(1)));
1. SHOW WAREHOUSES;
2. INSERT INTO VWH_META
SELECT CURRENT_TIMESTAMP(), *
FROM TABLE(RESULT_SCAN(LAST_QUERY_ID()));
1. SHOW WAREHOUSES;
2. INSERT INTO VWH_META
SELECT CURRENT_TIMESTAMP(),
OBJECT_CONSTRUCT(*)
FROM TABLE(RESULT_SCAN(LAST_QUERY_ID()));
1. SHOW WAREHOUSES;
2. INSERT INTO VWH_META
SELECT CURRENT_TIMESTAMP(), *
FROM TABLE(RESULT_SCAN(SELECT
LAST_QUERY_ID(-1)));
Answer:
CExplanation:
Snowflake administrators can capture virtual warehouse metadata by combining SHOW WAREHOUSES with RESULT_SCAN and OBJECT_CONSTRUCT.
The SHOW WAREHOUSES command returns information about accessible warehouses, including names, sizes, operational states, configuration settings, and other metadata.
RESULT_SCAN(LAST_QUERY_ID()) exposes the result of the preceding SHOW statement as a queryable result set.
The OBJECT_CONSTRUCT(*) function transforms each result row into a structured OBJECT containing column names as keys and corresponding values as attributes. Snowflake can store this object directly in a VARIANT column.
Option C correctly produces two values per inserted row: CURRENT_TIMESTAMP() for the snapshot time and OBJECT_CONSTRUCT(*) for the configuration data.
Option A does not provide the required configuration object and uses LAST_QUERY_ID(1), which references the first session query rather than necessarily the preceding SHOW statement.
Option B returns multiple metadata columns instead of constructing the single VARIANT value required by VWH_META.
Option D has an invalid RESULT_SCAN expression and likewise fails to construct the configuration object.
Technical qualification: OBJECT_CONSTRUCT omits attributes whose values are SQL NULL. Thus, the solution records available non-null metadata rather than necessarily preserving every possible configuration attribute. The result also depends on which warehouses the executing role can access.
Official Snowflake references: SHOW WAREHOUSES; RESULT_SCAN; LAST_QUERY_ID; OBJECT_CONSTRUCT.
A company has configured Snowflake replication between two Snowflake accounts, both running Snowflake Enterprise Edition. Replication applies to database APP_DB, which contains only one schema, APP_SCHEMA. The company’s Time Travel retention policy is currently 30 days in both accounts. An Administrator must extend the Time Travel retention policy to 60 days on the secondary database only.
How can this requirement be fulfilled?
Options:
Set the data retention policy on the secondary database to 60 days.
Set the data retention policy on the schemas in the secondary database to 60 days.
Set the data retention policy on the primary database to 30 days and the schemas to 60 days.
Set the data retention policy on the primary database to 60 days.
Answer:
AExplanation:
Snowflake database replication synchronizes supported database objects and data between the primary and secondary accounts. However, it does not replicate every database-level configuration parameter.
Option A is correct because the DATA_RETENTION_TIME_IN_DAYS parameter can be configured independently at the secondary database level.
Snowflake explicitly documents that database-level parameter settings on secondary databases are not overwritten by replication refreshes from the primary database.
For example, an appropriately authorized administrator can configure:
ALTER DATABASE APP_DB
SET DATA_RETENTION_TIME_IN_DAYS = 60;
This establishes a 60-day database-level retention setting on the secondary while leaving the primary database's 30-day setting unchanged.
Option B is unsuitable because schema-level parameters explicitly configured on the primary database can be replicated and overwrite the corresponding secondary schema settings.
Option C changes the primary configuration and does not meet the requirement to extend retention only on the secondary.
Option D changes the primary database's retention rather than the secondary's.
Both accounts use Enterprise Edition, which permits Time Travel retention of up to 90 days for permanent objects.
Technical qualification: If APP_SCHEMA or its tables already have an explicitly configured 30-day retention period, changing the secondary database default does not automatically override those settings. Such inherited and explicitly replicated parameters must be examined before claiming that every table will retain 60 days of history. Increasing retention also cannot recover historical versions already purged.
Official Snowflake references: Introduction to Database Replication Across Multiple Accounts — Parameters; ALTER DATABASE; Understanding & Using Time Travel.
In which scenario does using an external table simplify a data pipeline?
Options:
When accessing a Snowflake table from a relational database
When accessing a Snowflake table from an external database within the same region
When continuously writing data from a Snowflake table to external storage
When accessing a Snowflake table that references data files located in cloud storage
Answer:
DExplanation:
Snowflake external tables provide a relational interface for querying structured and semi-structured data files stored outside Snowflake, typically in cloud object storage such as Amazon S3, Azure Blob Storage, or Google Cloud Storage.
An external table references files through an external stage. Snowflake maintains file-level metadata and exposes the external data through a table-like abstraction, allowing SQL queries without requiring an initial COPY INTO operation to populate an internal Snowflake table.
This simplifies data pipelines when source files must remain in cloud storage, particularly for data lakes, historical archives, and externally managed datasets.
Option A describes accessing Snowflake from another relational database, which is not the purpose of an external table.
Option B similarly concerns external database connectivity rather than querying files stored in an external stage.
Option C describes exporting data from Snowflake to external storage, a process generally implemented through unloading operations such as COPY INTO a storage location.
Option D correctly identifies the external-table use case.
External tables are read-only and do not support conventional INSERT, UPDATE, or DELETE operations. Query performance may also be lower than native Snowflake tables because the underlying data remains externally stored.
Official Snowflake references: Introduction to External Tables; Creating External Tables; Querying External Tables.
A company has many users assigned to the ANALYST role who regularly query Snowflake through a reporting tool. The Administrator observes that the ANALYST users continuously keep two small clusters busy and occasionally require three or four clusters of that same size.
B. ased on this scenario, how should the Administrator configure a virtual warehouse to MOST efficiently support this user group?
Options:
Create a multi-cluster warehouse with MIN_CLUSTERS set to 1. Give MANAGE privileges to the ANALYST role so this group can start and stop the warehouse, and increase the number of clusters as needed.
Create a multi-cluster warehouse with MIN_CLUSTERS set to 2. Set the warehouse to auto-resume and auto-suspend, and give USAGE privileges to the ANALYST role. Allow the warehouse to auto-scale.
Create a standard X-Large warehouse, which is equivalent to four small clusters. Set the warehouse to auto-resume and auto-suspend, and give USAGE privileges to the ANALYST role.
Create four virtual warehouses (sized Small through XL) and set them to auto-suspend and auto-resume. Have users in the ANALYST role select the appropriate warehouse based on how many queries are being run.
Answer:
BExplanation:
A Snowflake multi-cluster warehouse is appropriate when workloads generate consistent query concurrency with occasional increases in demand.
The scenario indicates that two Small clusters are required for routine activity, with temporary increases to three or four clusters during busier periods.
Option B correctly establishes a baseline of two clusters and allows Snowflake to automatically increase capacity when concurrent query demand grows.
When query activity declines, additional clusters can be removed according to the warehouse's scaling policy. AUTO_SUSPEND and AUTO_RESUME provide additional controls to prevent unnecessary compute usage during periods of inactivity.
The ANALYST role requires only USAGE to execute queries, preserving least-privilege access without permitting warehouse configuration changes.
Option A is unsuitable because manual cluster management introduces unnecessary administrative responsibility. Moreover, MANAGE is not the applicable object-level privilege for the described warehouse operations.
Option C confuses warehouse size with independent cluster capacity. A single X-Large warehouse does not provide the same concurrency-scaling behavior as four independently managed Small clusters.
Option D introduces operational complexity and requires users to select warehouses manually.
Terminology warning: The original choices use MIN_CLUSTERS. The actual Snowflake configuration parameter is MIN_CLUSTER_COUNT. Option B is conceptually correct, but its wording should be corrected before publication.
Official Snowflake references: Multi-cluster Warehouses; CREATE WAREHOUSE; Access Control Privileges.
If a query matches the definition, will Snowflake always dynamically rewrite the query to use a materialized view?
Options:
No, because joins are not supported by materialized views.
No, because the optimizer might decide against it.
No, because the materialized view may not be up-to-date.
Yes, because materialized views are always faster.
Answer:
BExplanation:
Snowflake's query optimizer can automatically rewrite eligible queries to access materialized views instead of scanning their underlying base tables. However, the existence of a matching materialized view does not guarantee that it will be selected.
Option B correctly identifies the optimizer's cost-based decision process.
Snowflake evaluates available execution strategies and may choose to scan the base table when doing so is expected to provide equivalent or better performance. For example, effective micro-partition pruning on a well-clustered base table can make direct access more efficient than using a materialized view.
Option A is incorrect as an explanation of this behavior. Although Snowflake imposes restrictions on materialized-view definitions, including joins, the optimizer can still use materialized views when optimizing eligible queries involving other tables.
Option C is incorrect because materialized-view maintenance does not require queries to return stale data. Snowflake can reconcile changes from the base table to provide current results.
Option D incorrectly assumes that materialized views always outperform base-table access.
Administrators should inspect EXPLAIN output and Query Profile to determine whether the optimizer selects a materialized view. They should also account for automatic materialized-view maintenance costs when evaluating overall performance and credit efficiency.
Official Snowflake references: Working with Materialized Views: How the Query Optimizer Uses Materialized Views.
MY_TABLE is a table that has not been updated or changed for several days. On 01 January 2021 at 07:01, a user ran a query that updated this table. The query ID is '8e5d0ca9-005e-44e6-b858-a8f5b37c5726'. It is now 07:30 on the same day.
Which queries allow the user to view the historical data that was in the table before this query ran?
Choose three
Options:
SELECT * FROM my_table WITH TIME_TRAVEL(OFFSET = > -60*30);
SELECT * FROM my_table AT(TIMESTAMP = > '2021-01-01 07:00:00'::timestamp);
SELECT * FROM TIME_TRAVEL('MY_TABLE', 2021-01-01 07:00:00);
SELECT * FROM my_table PRIOR TO STATEMENT '8e5d0ca9-005e-44e6-b858-a8f5b37c5726';
SELECT * FROM my_table AT(OFFSET = > -60*30);
SELECT * FROM my_table BEFORE(STATEMENT = > '8e5d0ca9-005e-44e6-b858-a8f5b37c5726');
Answer:
B, E, FExplanation:
Snowflake Time Travel enables administrators to query historical table versions within the configured data-retention period. The AT and BEFORE clauses support recovery based on timestamps, relative time offsets, and statement identifiers.
Option B is correct because AT(TIMESTAMP = > ...) retrieves the table's historical state at the specified timestamp. Since the update occurred at 07:01, querying the table at 07:00 retrieves its preceding state.
Option E is correct because OFFSET specifies a relative number of seconds. At the hypothetical current time of 07:30, -60*30 refers to 07:00, before the update.
Option F is correct because BEFORE with a STATEMENT parameter retrieves the table state immediately before the specified statement completed.
Options A, C, and D use unsupported Time Travel syntax.
Snowflake requires historical data to remain within the table's retention period. Additionally, the STATEMENT parameter must identify a qualifying query executed within the previous 14 days.
Current-version qualification: The scenario is explicitly set on January 1, 2021. These statements are valid in that historical context; they cannot be used today to recover January 2021 data unless an applicable historical recovery mechanism still retains it. Timestamp interpretation also depends on Snowflake's timestamp type and session time zone.
Official Snowflake references: AT | BEFORE; Understanding & Using Time Travel.
An Administrator must create a sample from the LINEITEM table. The sample must not be repeatable, and the sampling function must select data in blocks of rows.
Which SELECT command generates a sample of 20% of the table?
Options:
select * from LINEITEM sample bernoulli (20);
select * from LINEITEM sample system (20);
select * from LINEITEM tablesample block (20 rows);
select * from LINEITEM tablesample system (20) seed (1);
Answer:
BExplanation:
Snowflake supports statistical sampling through the SAMPLE and TABLESAMPLE SQL clauses. The two principal sampling methods are BERNOULLI, also called ROW sampling, and SYSTEM, also called BLOCK sampling.
SYSTEM sampling evaluates blocks of rows rather than independently selecting individual rows. The specified percentage represents the probability that each block will be included in the resulting sample.
Option B is correct because:
SELECT *
FROM LINEITEM
SAMPLE SYSTEM (20);
selects blocks using a 20% inclusion probability without specifying a deterministic random seed.
Consequently, subsequent executions may select different blocks and produce different samples.
Option A uses BERNOULLI sampling, which evaluates rows individually rather than selecting blocks.
Option C is incorrect because SYSTEM or BLOCK sampling does not support fixed-row-count sampling through the proposed syntax.
Option D uses the correct block-based sampling method but supplies SEED (1), requesting reproducible sampling behavior. This contradicts the requirement that the sample not be repeatable.
An important distinction is that SYSTEM (20) does not guarantee exactly 20% of the table's rows. Because Snowflake selects entire blocks probabilistically, the actual number of sampled rows can vary depending on block composition and selection.
Official Snowflake references: SAMPLE / TABLESAMPLE: Sampling Methods; Probability; SEED / REPEATABLE.
